MICCAI COLAS 2026
Patient-Agnostic Spine Registration in Real Time
A hierarchical multi-agent Soft Actor-Critic framework that aligns a preoperative CT volume with intraoperative C-arm X-rays in six degrees of freedom — submillimeter accurate, and fast enough for the operating theatre.
Darshan K. N.1,2, Sriram L2,*, Sarath P.2,*, Vivek Maik2, Manojkumar Lakshmanan2, and Mohanasankar Sivaprakasam1,†
1 Dept. of Electrical Engineering, Indian Institute of Technology Madras, India2 Healthcare Technology Innovation Centre (HTIC), IIT Madras, India
* Equal contribution·† Corresponding author
Figure 1
SpineSAC Architecture
A CT volume and a calibrated AP/LP C-arm pair go in; the pose is mapped into canonical coordinates and refined by three SAC agents at increasing resolution.
Validated across C-arm systems, sawbone phantoms and cadaver anatomy
40 / 10 / 9train · val · test split
Abstract
- Task
- Intraoperative 2D–3D vertebral registration
- Input
- AP + LP C-arm X-rays, projection matrices, preoperative CT
- Output
- Registered 6-DoF vertebral pose [rx, ry, rz, tx, ty, tz]
- Data
- 59 AP–LP acquisition scenarios, three sawbone phantoms, cadaver validation
We propose SpineSAC, a hierarchical multi-agent Soft Actor-Critic framework that performs autonomous six-degrees-of-freedom vertebral registration in a patient-agnostic manner.
Aligning CT to C-arm imagery is a foundational step in image-guided spinal surgery. Conventional iterative optimisation reaches submillimeter accuracy but is far too slow for real-time use, while learning-based methods generalise poorly across patient anatomies and imaging systems. SpineSAC addresses both limitations at once.
A PCA-based canonical coordinate system maps poses from any CT scanner or C-arm into a unified anatomical frame; a rotational feature encoder condenses AP and LP DRR–X-ray pairs into a compact rotation-aware embedding; and three SAC agents refine the pose sequentially at increasing resolution. On sawbone phantoms the method reaches a target registration error of 1.45 ± 0.5 mm, and 2.31 mm on cadaver data, with a 9× inference speedup over the computational baseline.
One Frame for Every Patient
The principal axes of the bone voxels define a canonical coordinate system, so a pose measured on one scanner means the same thing on any other. A policy trained on one anatomy transfers to unseen patients without retraining.
See the Method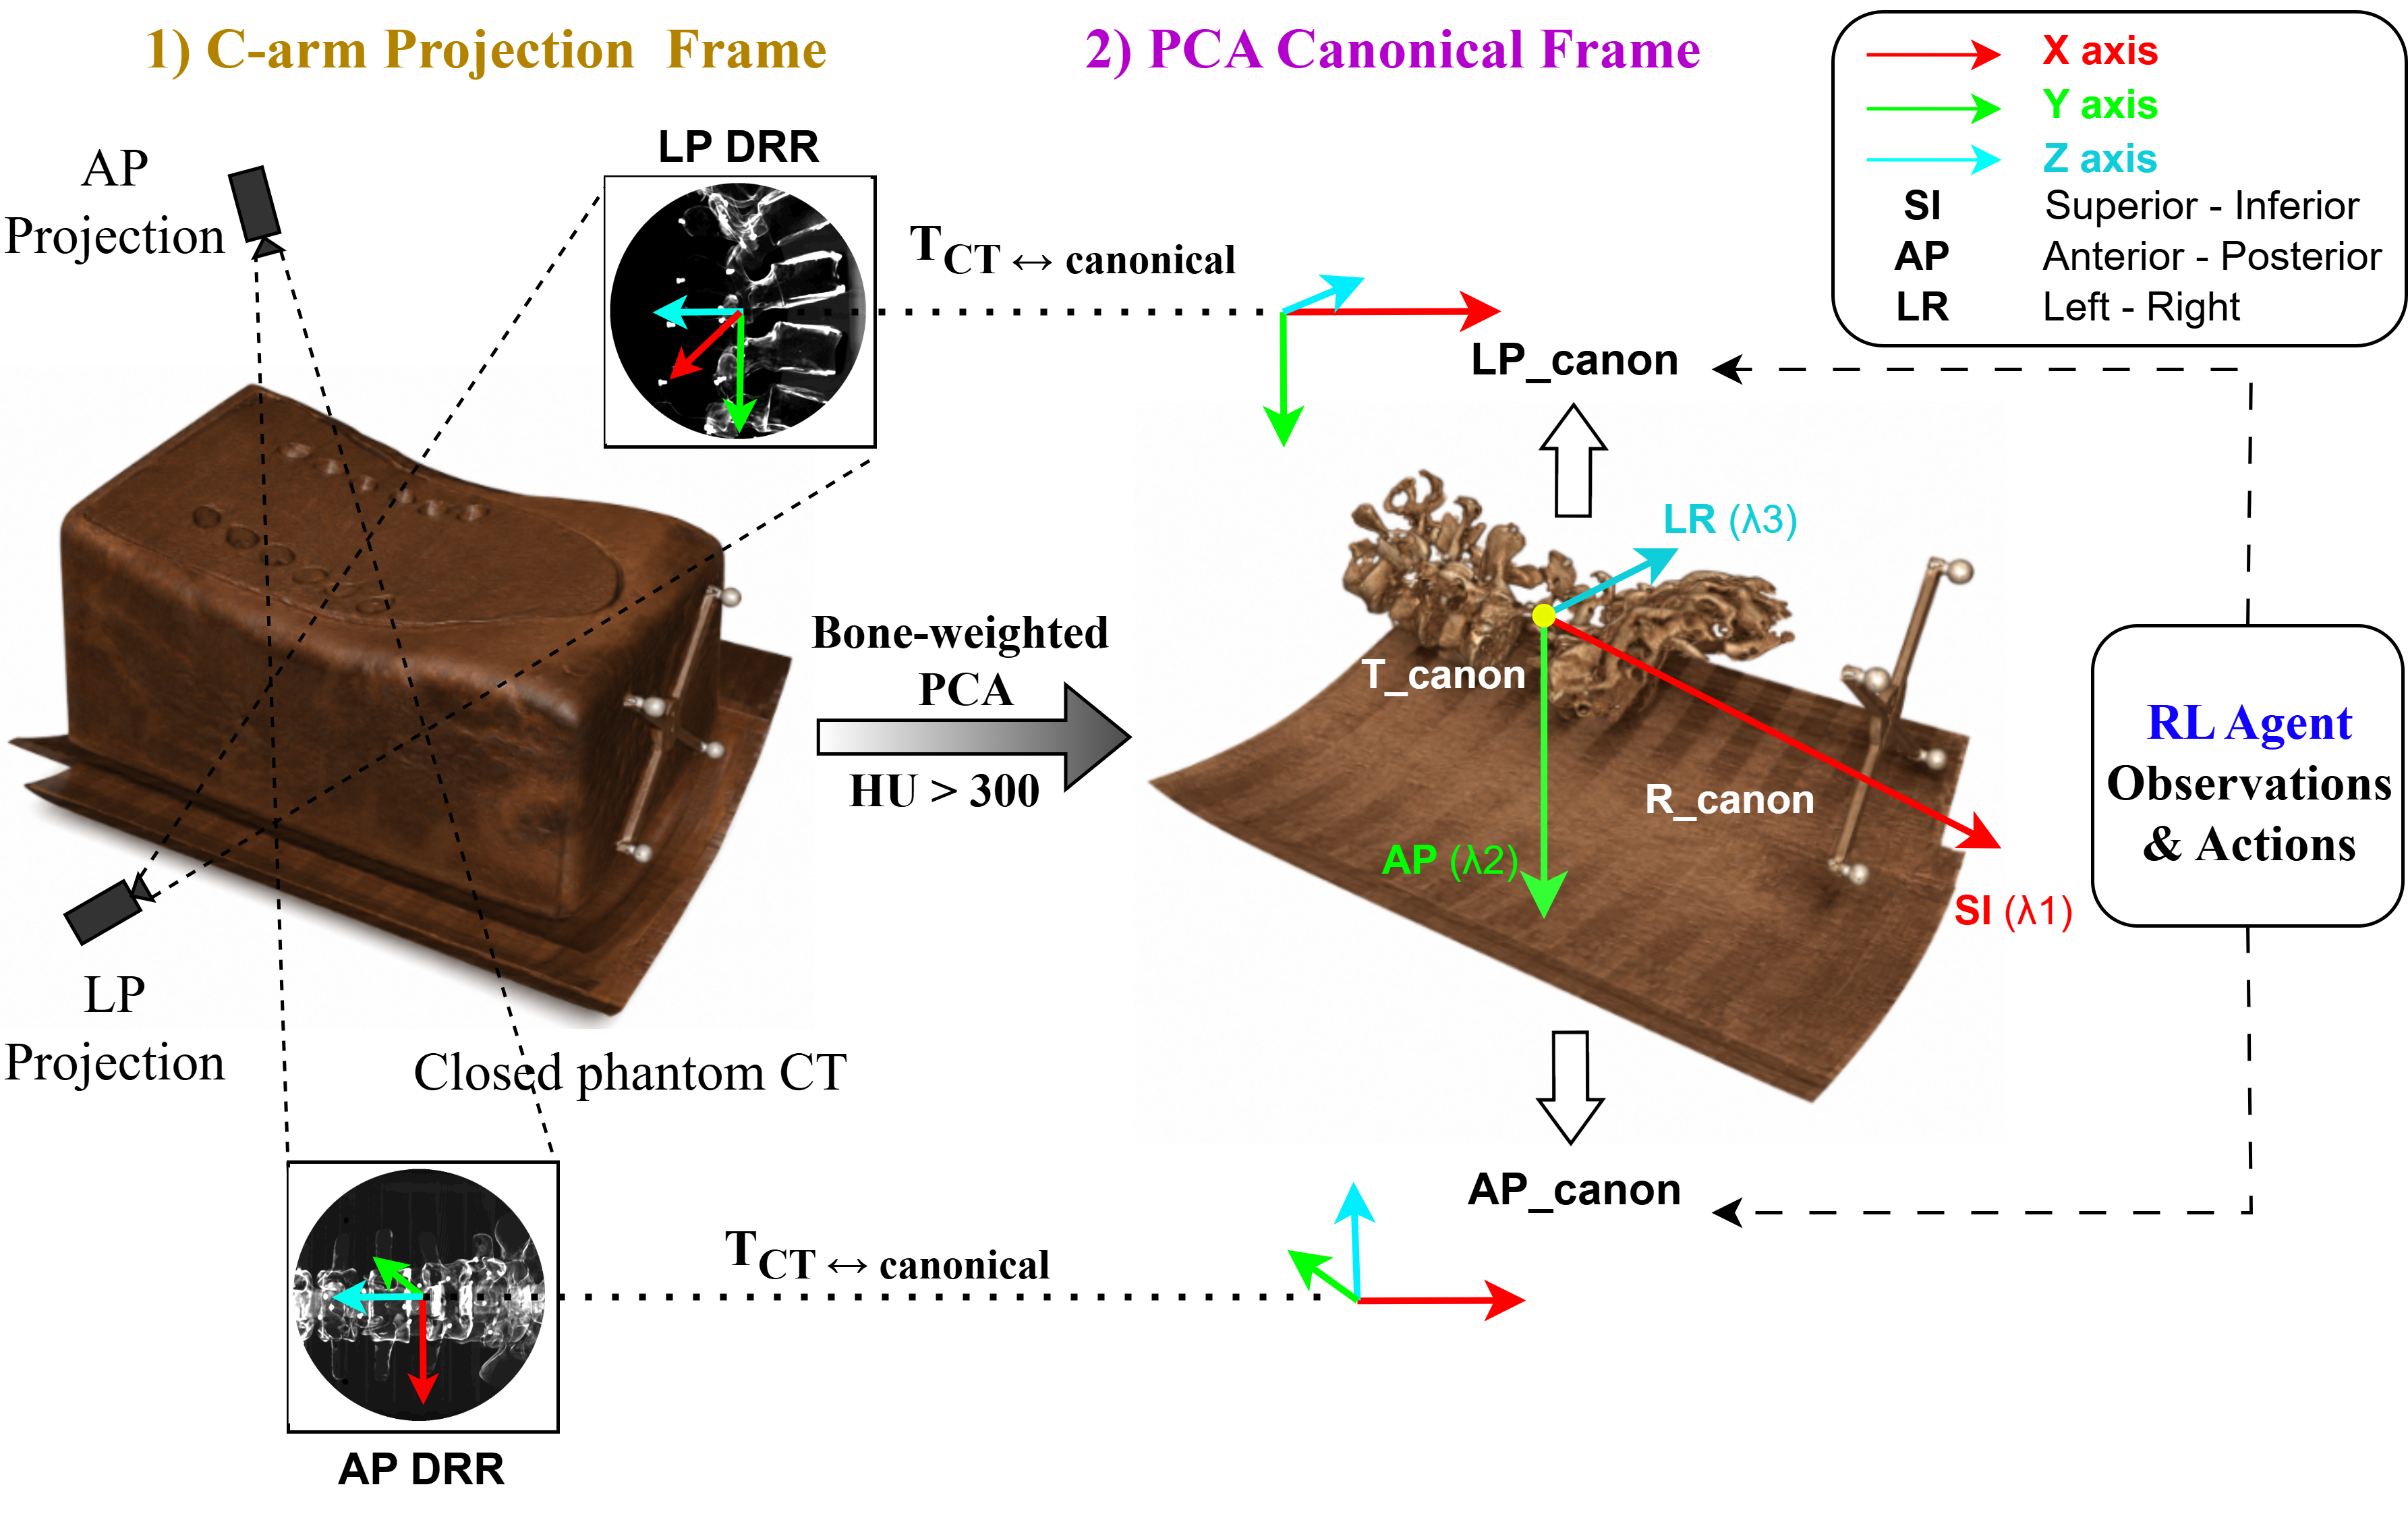
Rotation, Measured Directly
The rotational feature encoder is an equivariant Siamese network: AP and LP DRR–X-ray pairs pass through shared R2Conv branches, geometry heads and a multi-view fusion step, collapsing into a 16-d embedding of the remaining rotational misalignment — a geometrically grounded observation rather than raw pixels.
How It Trains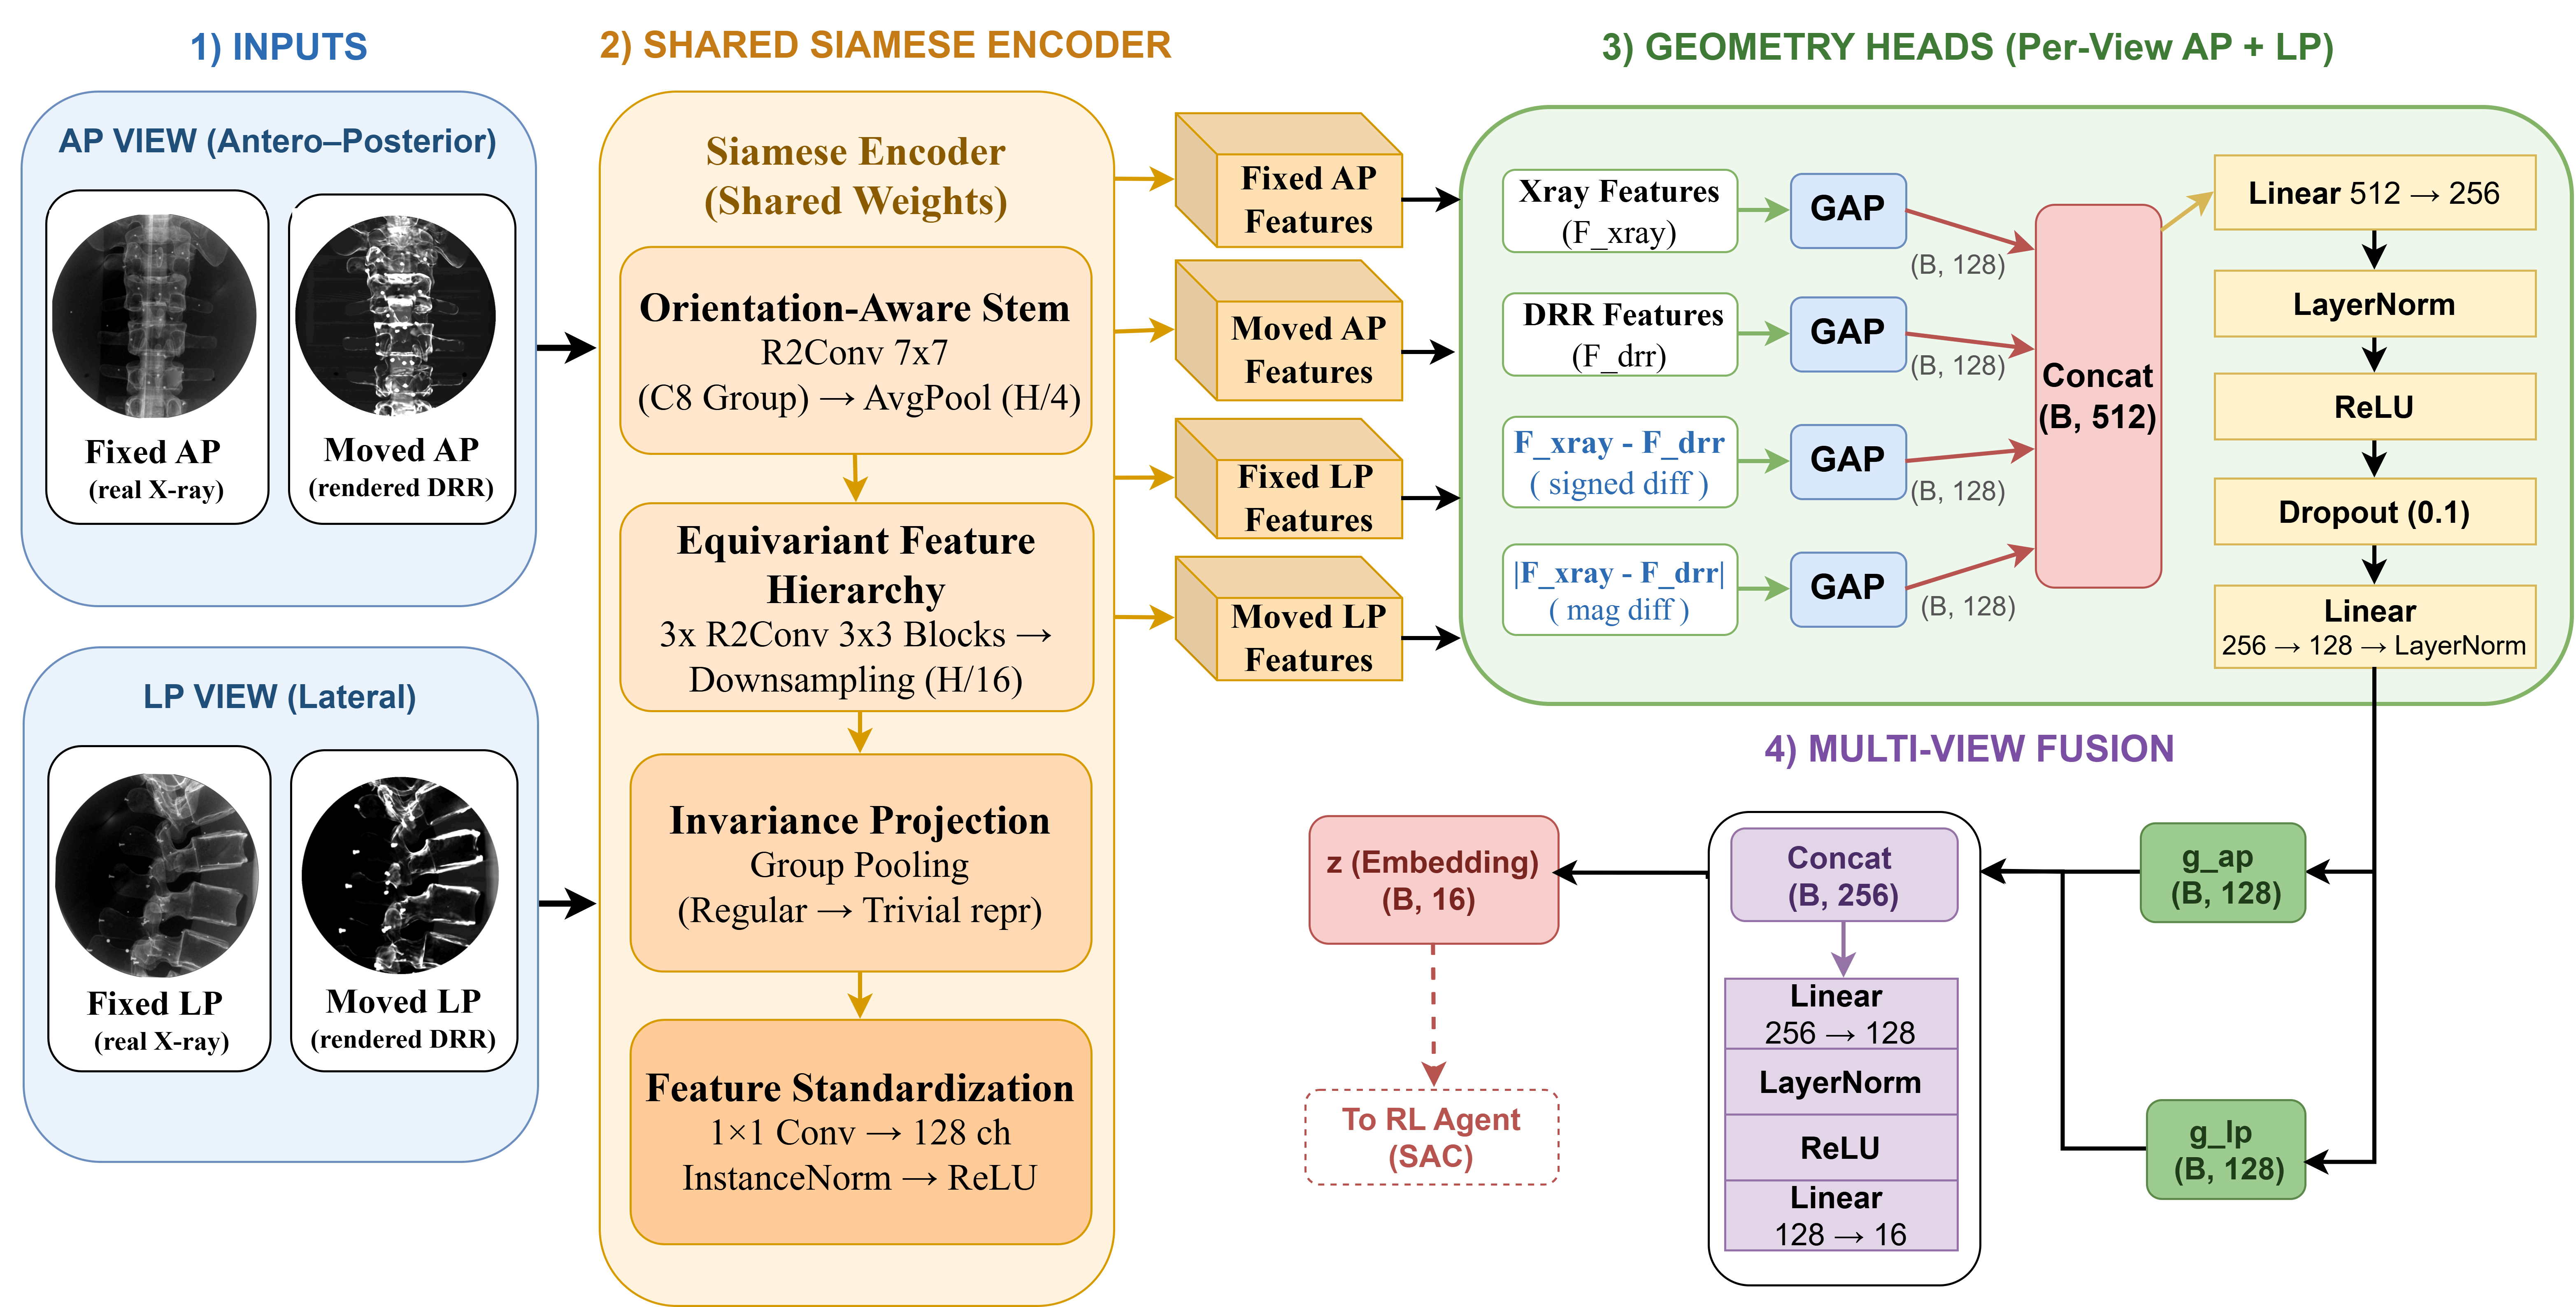
At a Glance
Submillimeter Accuracy. Operating-Room Speed.
A reinforcement learning formulation that keeps the accuracy of iterative optimisation while collapsing its runtime — and generalises past the patient it was trained on.
Patient-Agnostic
A PCA canonical frame maps poses from any CT scanner or C-arm into one anatomical reference — no per-patient retraining.
Real-Time Speed
A full six-DoF registration completes in about 5 s against 45 s for the iterative optimisation baseline.
Submillimeter Class
1.45 ± 0.5 mm target registration error on held-out sawbone phantom scenarios.
Rotation-Aware Features
An equivariant Siamese encoder condenses AP and LP DRR–X-ray pairs into a compact 16-d misalignment embedding.
Hierarchical Agents
Three SAC agents at rising resolution and shrinking capture range, each owning one band of the error distribution.
Clinically Validated
The phantom-trained policy transfers unchanged to cadaver acquisitions at 2.0–2.5 mm TRE.
Method
Six stages from two radiographs to a registered pose
Two X-ray views, their calibrated projection matrices and a preoperative CT go in. A registered 6-DoF vertebral pose comes out, in about five seconds.
Rather than learning one policy for one anatomy, SpineSAC learns a policy in a frame where every rotation and translation carries the same anatomical meaning across patients.
- 01
Initial pose estimation
Landmark correspondences between the AP and LP views give a starting 6-DoF estimate for the target vertebra — the pose the agents begin from.
- 02
PCA canonical transform
The principal axes of the bone voxels define a canonical coordinate system. Poses from any CT scanner or C-arm map into one anatomical reference frame, so a policy trained on one patient transfers to unseen patients without retraining.
- 03
Rotational feature encoder
An equivariant Siamese network condenses the AP and LP DRR–X-ray pairs into a 16-d rotational misalignment embedding, giving the agent a geometrically grounded observation. It feeds the 43-d state vector each agent sees.
- 04
Agent 0 — coarse registration
Renders at 256 px over a ±20°/mm capture range for up to 40 steps, pulling a badly misaligned initial pose into the neighbourhood of the solution.
- 05
Agent 1 — medium refinement
Takes over at 512 px with a tightened ±10°/mm range and 40 steps, trading capture range for precision now that the coarse error is gone.
- 06
Agent 2 — fine registration
Runs at 1024 px within ±5°/mm for up to 70 steps. At every step the updated pose drives a VTK DRR renderer, and the rendered DRR is compared against the intraoperative X-ray to form the next observation and reward.
Contributions
Three are newVertebral poses from any scanner or C-arm are mapped into a unified anatomical frame derived from the principal axes of bone voxels, so each pose component means the same thing across datasets.
An equivariant Siamese network built on R2Conv layers, trained with geodesic, Huber and InfoNCE losses, producing a compact rotational misalignment embedding.
Three independent SAC agents at rising resolutions and shrinking capture ranges, each responsible for one band of the error distribution.
Training difficulty ramps with the agent's competence rather than starting at the full capture range.
Transitions are screened before entering the buffer, keeping the off-policy updates on informative experience.
Each agent is warm-started from the one below it, so the fine agent does not relearn the coarse policy from scratch.
Per-agent configuration
config.py| Agent | Resolution | Capture range | Max steps | Entropy target |
|---|---|---|---|---|
| Agent 0 — coarse | 256 px | ±20 °/mm | 40 | −1.5 |
| Agent 1 — medium | 512 px | ±10 °/mm | 40 | −3.0 |
| Agent 2 — fine | 1024 px | ±5 °/mm | 70 | −6.0 |
Shared across agents: learning rate 1e−4, batch size 512, discount 0.99, soft update coefficient 0.005, four gradient steps per environment step, actor and critic hidden dims [256, 128, 64].
Results
Registration on held-out phantom scenarios
The predicted pose shown as a DRR–X-ray overlay, against three reinforcement learning baselines trained on the same splits.
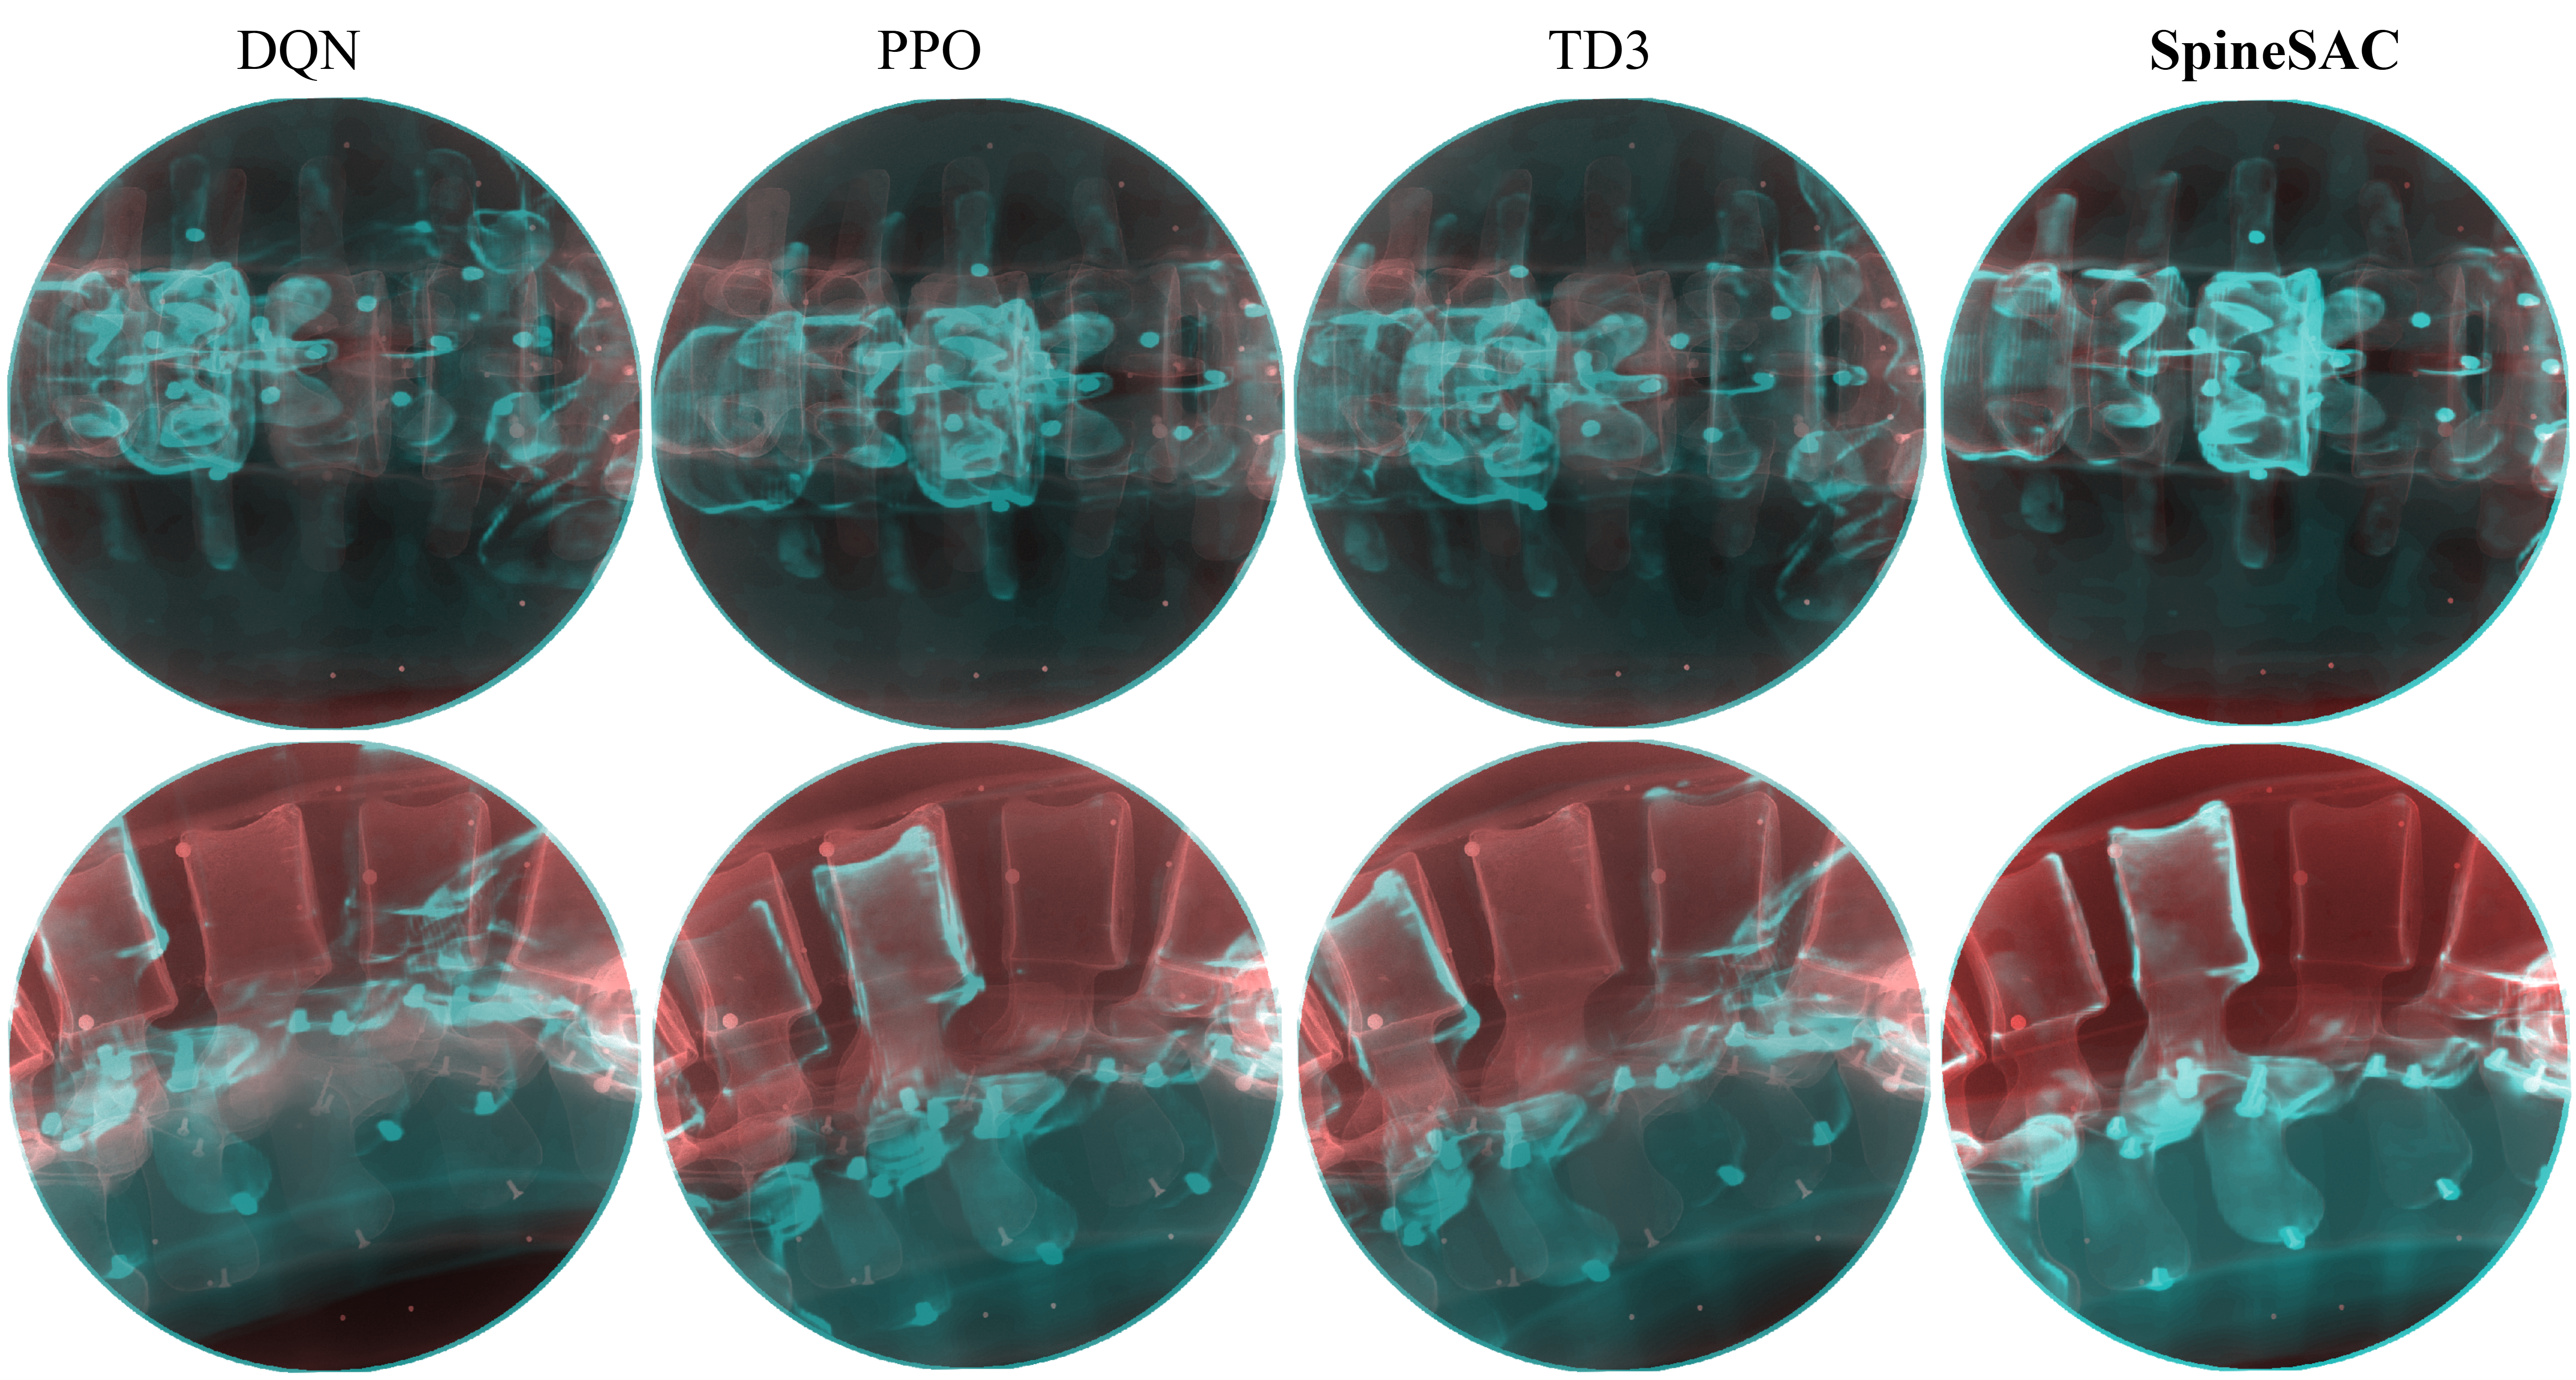
On the phantom dataset SpineSAC registers to a target registration error of 1.45 ± 0.5 mm — roughly a fourfold reduction over the TD3, PPO and DQN baselines, all of which remain above 5.7 mm.
Inter-architecture comparison
- TD35.76 ± 0.8
- DQN7.1 ± 0.6
- PPO6.6 ± 0.4
- SpineSAC(ours)1.4 ± 0.5best
Intra-ablation study
- Base SAC4.9 ± 0.5
- HMSAC2.74 ± 0.4
- HMSAC + CCS1.97 ± 0.5
- HMSAC + RFE1.68 ± 0.5
Table 1 — 8 methods, C-arm closed and open. SpineSAC is highlighted; the remaining rows are context. Switch to Table for every metric at once.
Inference and per-vertebra error
9× speedupA full registration completes in about 5 s against 45 s for the iterative baseline — a ninefold speedup, which is what moves the method from offline analysis into the operating theatre.
Per-region error across L3–L5 — right pedicle, left pedicle and spinous process — stays below 1.8 mm, so accuracy does not concentrate in one easy landmark.
Clinical validation — cadaver
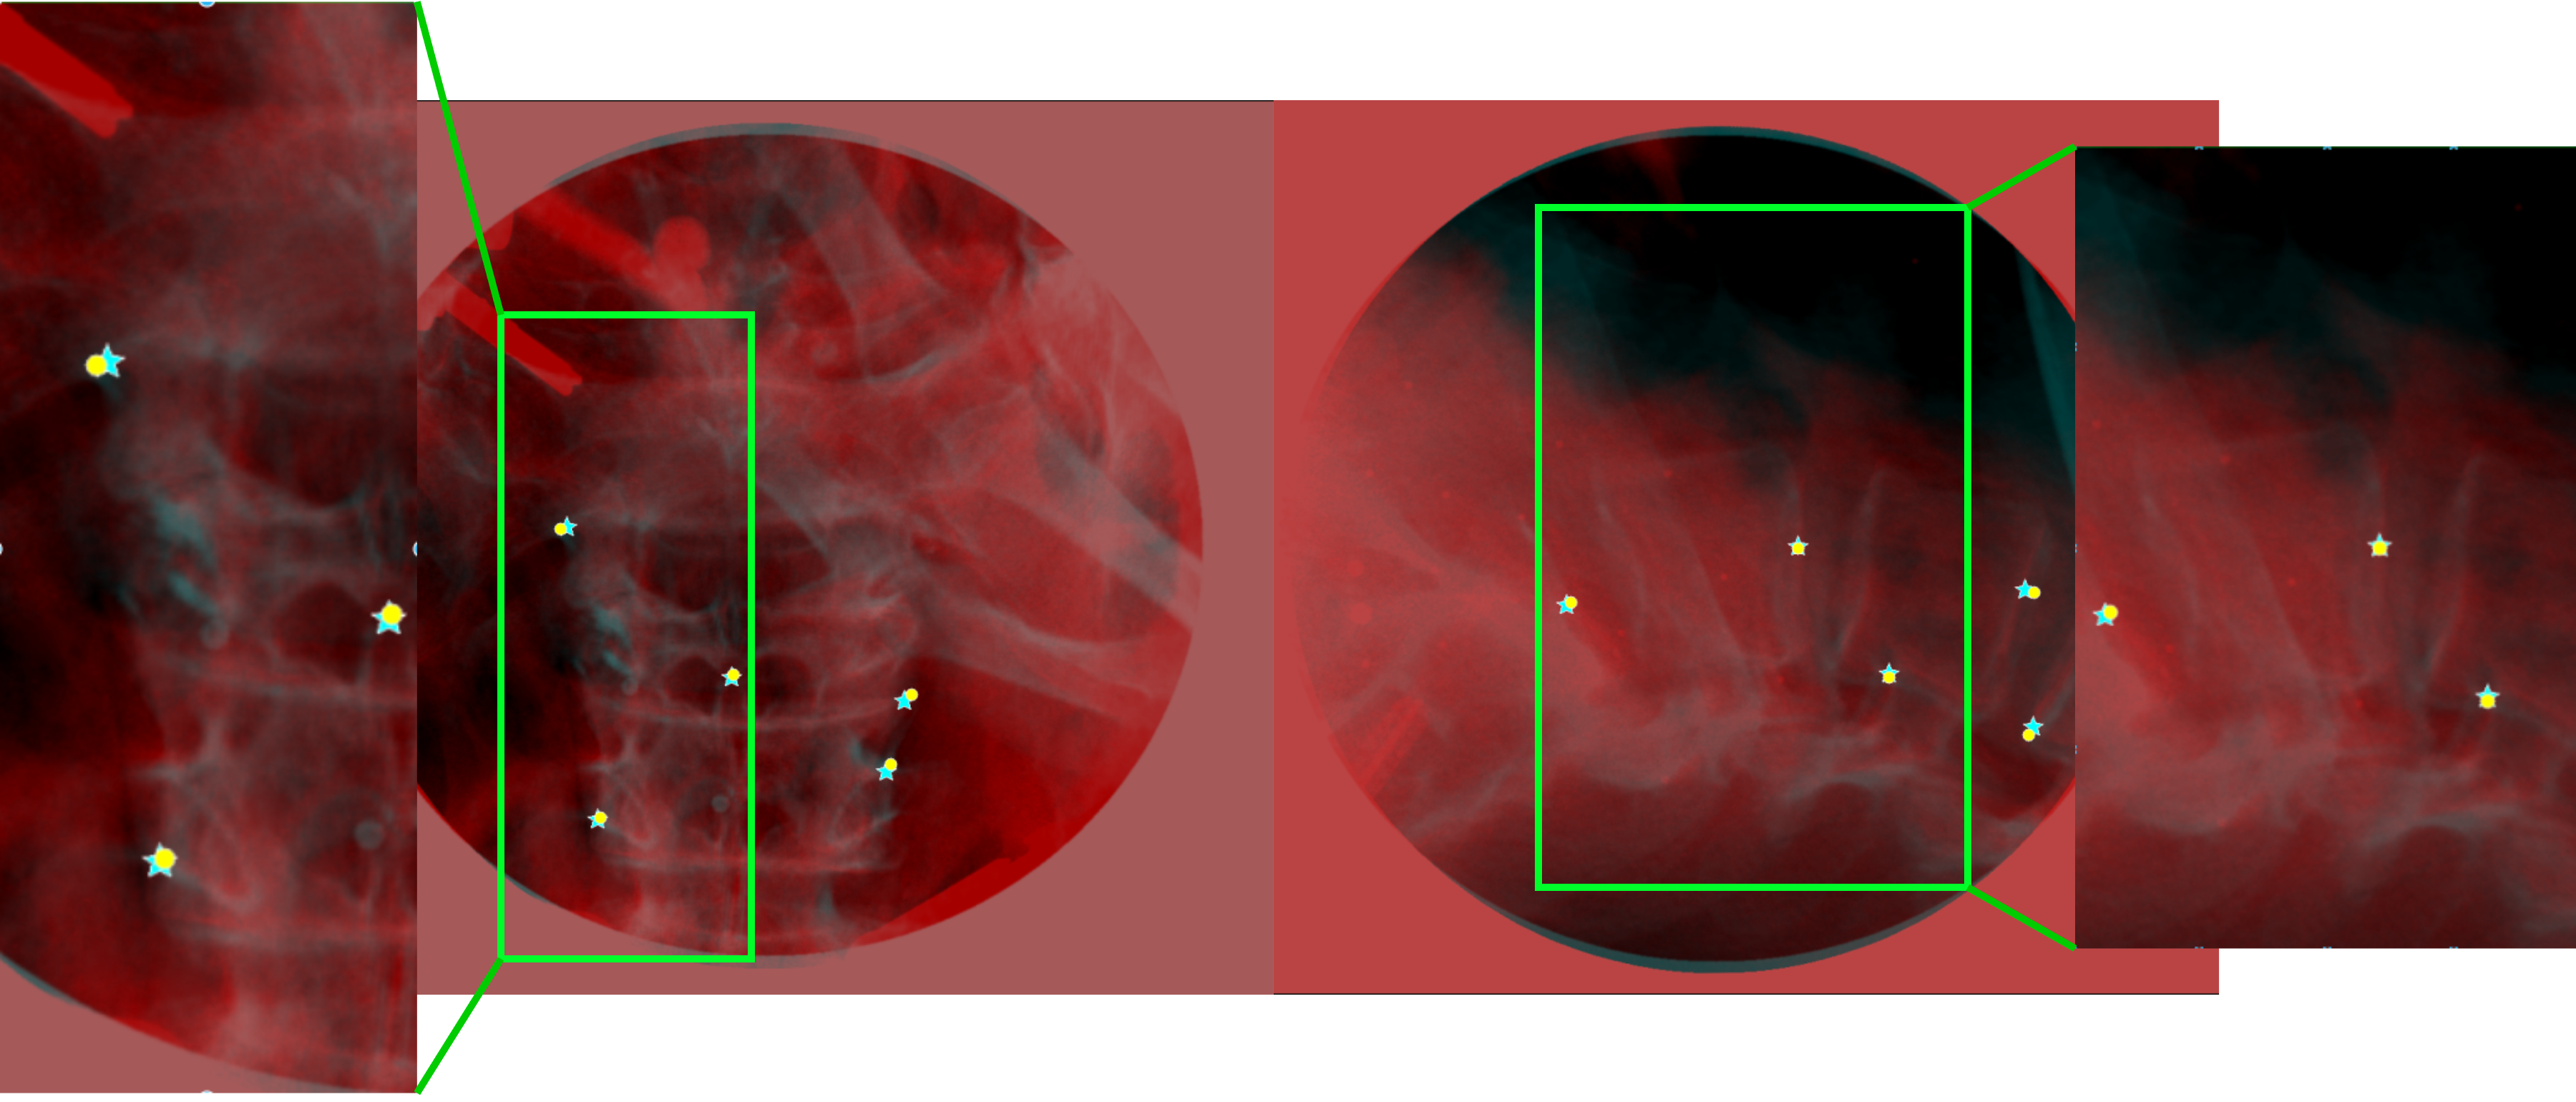
Real anatomyThe policy trained on sawbone phantoms was applied unchanged to cadaver acquisitions, with no patient-specific retraining.
Dataset
The full dataset is open-sourced
All 59 AP–LP X-ray acquisition scenarios, with paired projection matrices and CT volumes, released alongside pretrained weights.
The scenarios were collected from three sawbone phantoms — one closed, two open — across multiple C-arm systems with varying source-to-patient distances, X-ray intensities and C-arm orientations. The split is 40 / 10 / 9 for training, validation and testing.
Download from Google DriveDownload each subfolder individually and keep its original name; the relative paths in datasets.py then resolve with no manual edits.
ct_folderPreoperative CT volume (DICOM)xray_ap / xray_lpAP and LP intraoperative X-raysaplp_txtProjection matrix for both viewsx0Initial 6-DoF pose estimategt_poseGround-truth 6-DoF poseroi_ap / roi_lpVertebra ROI boxes per viewPretrained weights
Google DriveFinal three-agent policies — place under checkpoints/.
Rotational feature encoder — place under ../ckpts_v2/, as configured in config.py.
Code
Run it yourself
Linux is strongly recommended: the equivariant layers in the feature encoder need it for full functionality. Developed and tested on Ubuntu 20.04+ with CUDA 12.x.
Install
# NVIDIA L40S (46 GB) | CUDA 12.x | Python 3.10
conda create -n spinesac python=3.10 -y
conda activate spinesac

pip install torch torchvision \
  --index-url https://download.pytorch.org/whl/cu121

pip install -r requirements.txt
Train and evaluate
# validate the train/val/test splits
python data_splits.py

# epoch-based training
python train_tvt.py

# per-vertebra TRE reporting
python evaluate_3sac.py